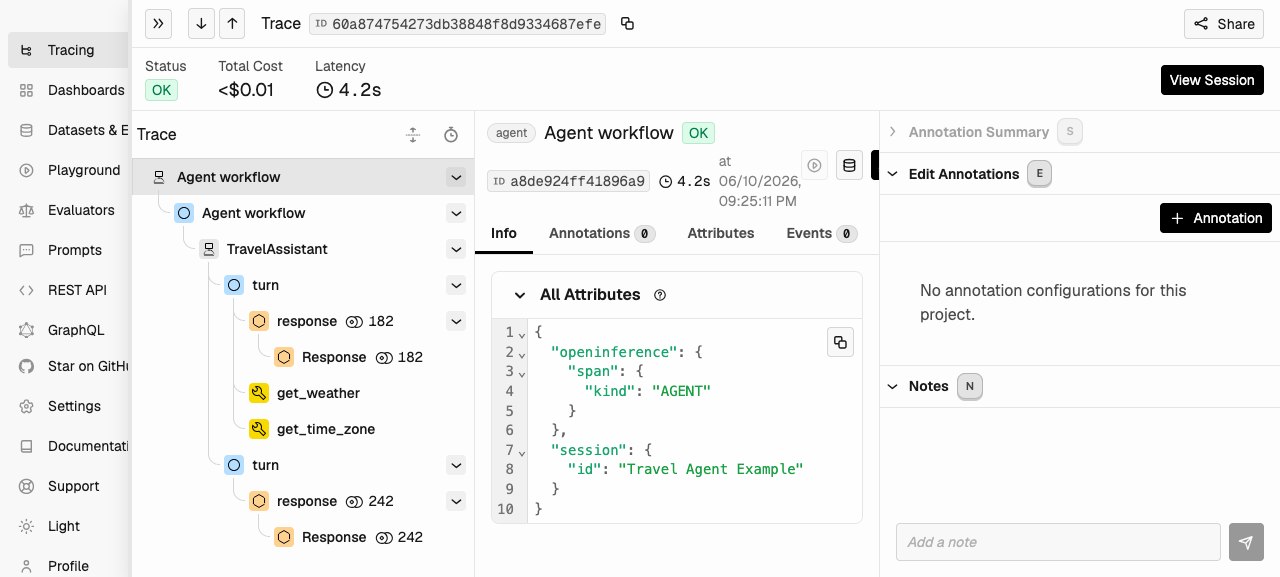
SERVER, CLIENT, PRODUCER, …). OpenInference adds an AI-specific set: LLM, Tool, Agent, Chain, Retriever, and more.
Span kind is what drives the span-kind icons in the Phoenix UI. It’s also how Phoenix knows which attributes to expect — an LLM span gets a different visual treatment from a tool span.
Setting the Span Kind
Span kind is set via theopeninference.span.kind attribute. The value is ALL CAPS — "TOOL", not "Tool". Casing matters: the canonical OpenInference Python enum is OpenInferenceSpanKindValues.TOOL = "TOOL".
Phoenix UI behavior: span-kind icons in Phoenix trace tree come directly from the
openinference.span.kind attribute. A span without that attribute renders with a blank icon. Auto-instrumentors set this for you — set it explicitly on every manual span.The Twelve Span Kinds
OpenInference defines twelve span-kind values. The first four (LLM, Chain, Agent, Tool) are the ones you’ll encounter most often:| Icon | Span kind | Description |
|---|---|---|
 | LLM | A call to a large language model. |
 | CHAIN | A starting point or a link between different LLM application steps. |
 | AGENT | A span that encompasses calls to LLMs and tools — typically the top-level wrapper for an agent loop. |
 | TOOL | A span that represents a call to an external tool, API, or function on behalf of an LLM. |
 | RETRIEVER | A data retrieval query for context from a datastore (e.g., a vector DB query). |
 | EMBEDDING | An encoding of unstructured data into a vector. |
 | RERANKER | A relevance-based re-ordering of documents. |
 | GUARDRAIL | A validation of LLM input or output for safety, policy, or compliance. |
 | EVALUATOR | An evaluation process — the type, configuration, and results. |
| DECISION | A call to a decision model — one that scores or selects among candidate options supplied in the request (routing, classification, rubric scoring) rather than generating free-form text. See DECISION. |
| PROMPT | A span representing prompt construction or templating. |
| UNKNOWN | Default when no kind is set explicitly. |
DECISION spans are new. Phoenix renders them with their own icon and a span view that names the decision model. The OpenInference instrumentors for the OpenAI Decisions API and TypeSafe AI System One emit them. The decision.* attributes are described under DECISION below and may still evolve as more decision-model providers appear.Common Attributes Across All Kinds
These attributes apply to every span kind. Auto-instrumentors set them automatically; set them yourself on every manual span:Phoenix UI behavior: Phoenix reads the trace-level input and output from the root span’s
input.value and output.value. If your root span doesn’t set them, the trace list view shows those columns as blank even if child spans have data.Per-Kind Attributes
The four most-used kinds, plus the newer DECISION kind, have a richer attribute set. The full list lives in the OpenInference semantic conventions — the tables below are a summary.LLM
A call to a large language model.TOOL
A call to an external tool, API, or function on behalf of an LLM.Tool calls are one of the clearest cases where you must instrument manually when making an LLM calls directly, instead of via a framework. When you call OpenAI directly, the auto-instrumentor traces the model’s request for a tool call — but the actual execution of the tool function happens in your Python code, where the instrumentor can’t see it. Wrap the function in a tool span yourself.
AGENT
A span that encompasses calls to LLMs and tools — typically the top-level wrapper for an agent loop.CHAIN
A starting point or a link between different application steps. Use a chain span to group pre/post-processing logic that doesn’t fit any of the more specific kinds. Chain spans use only the common attributes —input.value, output.value, metadata, session.id, etc.
DECISION
A call to a decision model. A decision model takes some state plus a fixed set of typed questions and returns one typed, probabilistic answer per question, instead of generating free-form text. Examples are the OpenAI Decisions API, which answers predicate, choice, and score questions over text or images, and TypeSafe AI’s System One / Jev, which answers Noul, Choice, and Score questions. Decision models suit the “smart if-statements” inside an application: routing a request to the right agent or department, classifying content, judging whether a condition holds, or scoring an item against a rubric. Decision spans use adecision.* namespace instead of llm.*, so decision-model usage stays out of LLM model, token, and cost reporting. The decision.* identification attributes mirror their llm.* counterparts and share the same well-known values (openai, typesafe, and so on).
Token counts have no prompt/completion split and no total, since a decision call has no chat-style prompt and completion. A decision call is not a chat exchange either, so decision spans carry no
llm.input_messages or llm.output_messages, and they should not set llm.system, llm.provider, llm.model_name, or llm.token_count.*.
Phoenix UI behavior: a DECISION span renders with the decision icon in the trace tree. Its details view shows the input and output cards, with the decision model named in the input card header. The name comes from
decision.model_name, then decision.response.model_name, then decision.request.model_name, and is led by the provider’s icon when Phoenix has one for decision.provider. Decision spans use decision.token_count.* rather than llm.token_count.*, so their usage does not appear in LLM token and cost totals.Other Kinds
The remaining seven span kinds — RETRIEVER, EMBEDDING, RERANKER, GUARDRAIL, EVALUATOR, PROMPT, UNKNOWN — each have their own attribute schemas. Consult the canonical source for the full per-kind attribute list.Multimodal Message Content
Inputs and outputs in modern AI applications aren’t always plain text. OpenInference defines amessage_content attribute family for multimodal content:
For audio specifically, OpenInference exposes a separate set of attributes —
audio.url, audio.mime_type, audio.transcript — see the canonical source.
How a Trace Tree Uses Span Kinds
A typical agent trace nests span kinds inside each other: